
ในบทความนี้
In this post
1. ปัญหาทางวิศวกรรม
เป้าหมายบทนี้
แสดงว่าโค้ดถูกไวยากรณ์ยังผิดโจทย์ได้ แล้วใช้ตัวอย่างที่เชื่อถือและ property ก่อนให้โมเดลประเมิน
candidate สูตร price - percent ผ่านตัวตรวจภาษาที่จำกัด แต่เมื่อ price=1999 และ percent=25 จะได้ 1974 ทั้งที่ requirement ต้องได้ 1499 นี่คือเหตุชัดที่สุดที่ต้องแยก shape จาก behavior parser ไม่รู้กติกาธุรกิจ และคำอธิบายที่โมเดลเขียนให้โค้ดตัวเองก็ไม่ใช่ oracle ที่เป็นอิสระ ใส่เลขที่ต้องตอบแน่นอนไว้ใน trusted test แล้วเก็บ semantic evaluation สำหรับคำถามที่ต้องตีความจริง
companion แปล return expression ที่ผ่าน validation ด้วย input จำนวนเต็มสองค่า ไม่รัน source เป็น Python ตัวอย่างที่ทีมดูแลหกกรณีครอบคลุมส่วนลดทั่วไป ศูนย์เปอร์เซ็นต์ ลดเต็ม ปัดเศษเซนต์ และราคาศูนย์ behavior_check คืน revise เมื่อ expression ที่อนุญาตให้ผลต่างจากค่าคาดหมาย การหารศูนย์และคำนวณเกินขอบเขตส่ง reject interpreter มีงบจำนวน node และขนาดค่า เพื่อไม่ให้ expression ที่รับแล้วสั่งคำนวณได้ไม่จำกัด
2. ขอบเขตที่ต้องออกแบบ
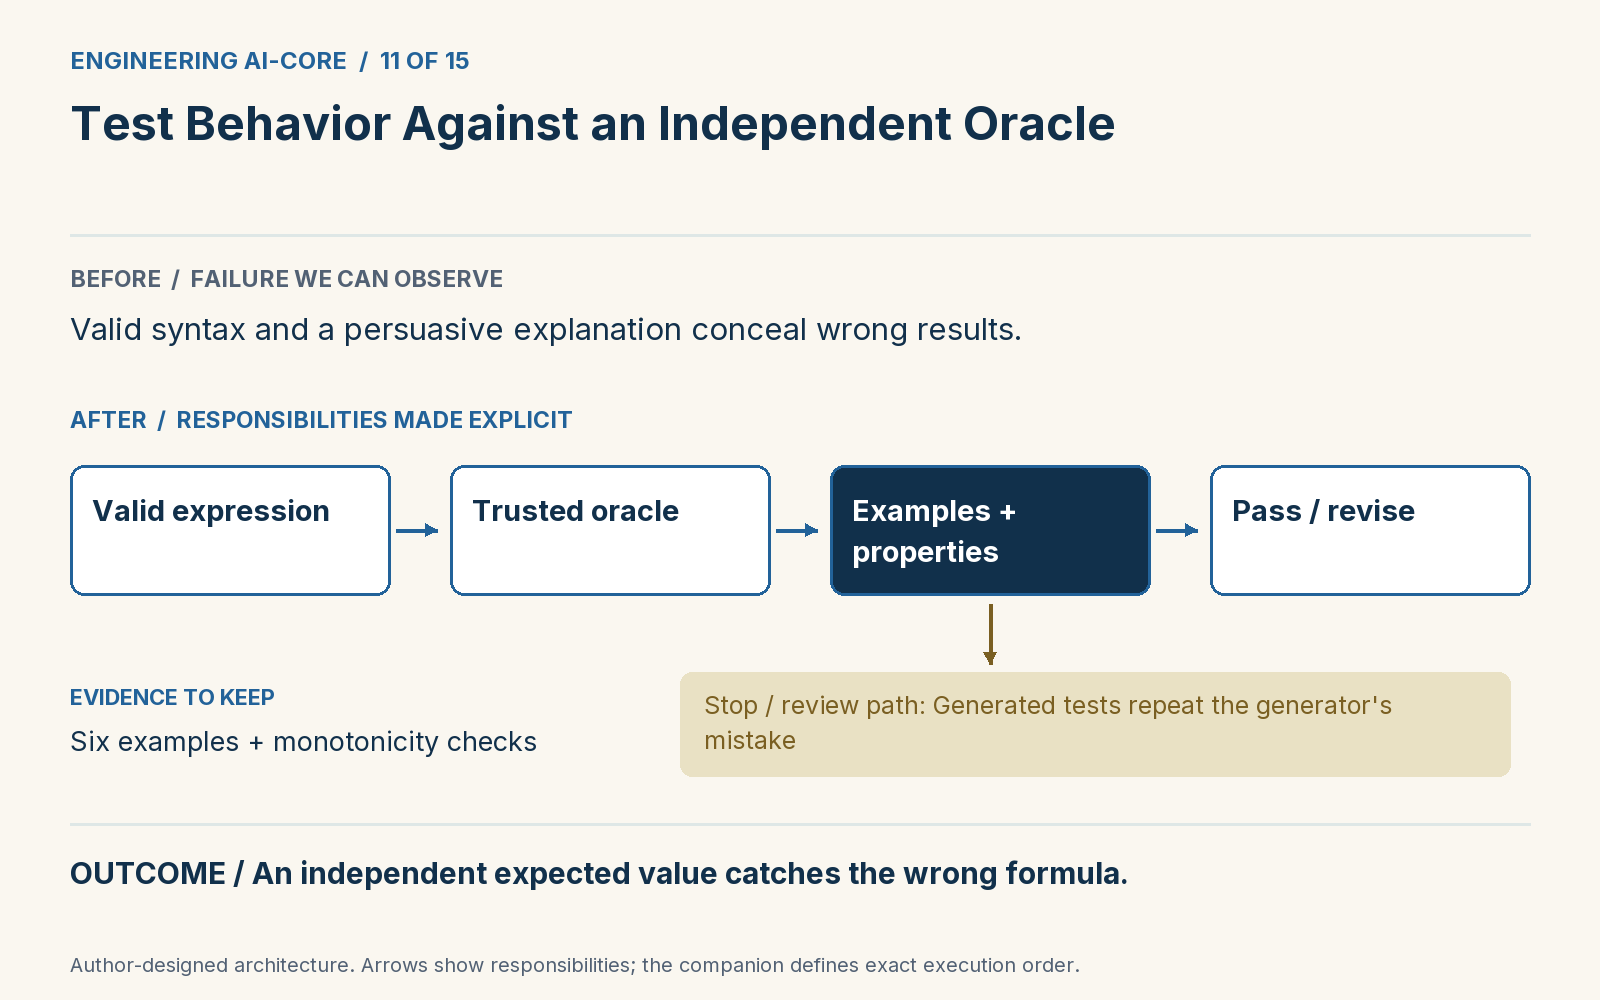
example test ยืนยันเฉพาะจุดที่เลือก test suite เพิ่ม monotonicity: เมื่อเพิ่ม percent จาก 0 ถึง 100 สำหรับราคาที่เลือก ผลต้องไม่ติดลบและไม่เพิ่มขึ้น ข้อนี้จับความผิดอีกประเภท แต่ยังไม่พิสูจน์เท่ากันทุก integer การเลือก property เป็นงานเขียน specification candidate ที่ตั้งใจหลบหรือ overfit อาจตรงตัวอย่างที่เห็นแต่ผิดจุดอื่น จึงต้องมี held-out และใช้วิธีพิสูจน์เข้มขึ้นเมื่อ domain หรือผลกระทบต้องการ
3. อ่าน implementation
ส่วนโค้ดจาก companion เพื่ออ่านประกอบ ใช้คำสั่งในหัวข้อ 5 เพื่อรันตัวอย่างที่ครบ dependency
def behavior_check(candidate):
    valid = output_check(candidate)
    if valid.state != "pass":
        return valid
    expression = ast.parse(candidate["source"]).body[0].body[0].value
    try:
        for price, percent, expected in CASES:
            if interpret(expression, {"price": price, "percent": percent}) != expected:
                return Gate("revise", "behavior_mismatch")
    except (ArithmeticError, ValueError, KeyError, RecursionError):
        return Gate("reject", "arithmetic_failure")
    return Gate("pass", "behavior_examples_pass")
ระบุ domain แยกด้วยว่า price เป็น integer ไม่ติดลบ และ percent เป็น integer ใน [0,100] service จริงต้องมี host validation ก่อนเรียก ตัวอย่างที่เชื่อถือในแล็บอยู่ใน domain นี้อยู่แล้ว อย่าอ่านฟังก์ชันที่แปลนี้ว่าเป็น pricing API ครบถ้วน ข้อจำกัดเชิงตัวเลขที่ TypeSafe ระบุช่วยสนับสนุนการแบ่งงาน [1] แต่ไม่จำเป็นต้องมีผลวัดโมเดลเพื่อยืนยันเหตุผลของ exact test ผลที่เห็นชัดคือ shape=pass, behavior=revise และเมื่อแก้เป็น price * (100 - percent) // 100 จึง behavior=pass
4. เปรียบเทียบผลที่ได้
| เส้นทาง | ผลที่สังเกตได้ |
|---|---|
| ก่อนเพิ่มด่านนี้ | ไวยากรณ์ถูกและคำอธิบายดีซ่อนผลผิด |
| หลังเพิ่มด่านนี้ | ค่าคาดหมายที่เป็นอิสระจับสูตรผิดได้ |
ผลต่อไปนี้มาจาก fixture ที่กำหนดคำตอบไว้เพื่อตรวจสถาปัตยกรรม ไม่ใช่ผลวัดความแม่น ความเร็ว หรือต้นทุนของ Jev จริง
{
  "shape": "pass",
  "behavior": "revise",
  "fixed": "pass",
  "trusted_examples": 6
}
5. รัน ทำให้พัง และอธิบาย
Part 11 code · Implementation · Tests: test_shape_does_not_imply_behavior · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 11
python3 -m unittest tests.test_boundaries.BoundaryTests.test_shape_does_not_imply_behavior -v
ลองทำด้วยตัวเอง
สร้างสูตรที่ผ่านตัวอย่างเดียวแต่ผิดกรณีขอบ แล้วเพิ่ม property ที่จับได้โดยไม่ลอก implementation มาสร้าง test
สิ่งที่ต้องส่ง: input ที่ลอง สถานะและเหตุผลที่ได้ และคำอธิบายว่าด่านใดเป็นผู้รับผิดชอบ ห้ามแก้ expected result เพียงเพื่อให้ test ผ่าน
6. แหล่งอ้างอิงและขอบเขต
เอกสารต้นทางและข้อจำกัด
ตรวจเอกสาร 2 พฤศจิกายน 2026 ตัวอย่างและ threshold เป็นการออกแบบเพื่อการสอน การอ้าง [1], [2] ตรงกับลำดับข้างล่าง ยังไม่ได้วัด live API
- TypeSafe, Jev 1.13 jaggedness — Math and NumbersVersion-specific motivation for keeping exact arithmetic in code.
1. The engineering problem
Learning outcome
Show why valid code can still be wrong, and use trusted examples plus properties before semantic grading.
The candidate price - percent passes our restricted-language validator. For price=1999 and percent=25 it returns 1974, while the declared requirement expects 1499. This is the cleanest reason to keep output shape separate from output behavior. A parser cannot know the business requirement. A model's explanation of its own code is also not an independent oracle. Put exact arithmetic in trusted tests and reserve semantic evaluation for questions that actually need interpretation.
The companion interprets the validated return expression with two integer inputs. It never executes the source as Python. Six maintained examples cover normal discounting, zero percent, full discount, fractional-cent rounding and zero price. behavior_check returns revise for a permitted expression whose result differs from an expected value. Division by zero and bounded-arithmetic failures reject. The interpreter has a small node and value budget so an admitted expression cannot request arbitrary computation.
2. The boundary to design
Example tests establish behavior only at their chosen points. The test suite adds a monotonicity property: as discount percent increases from 0 through 100 for selected prices, the result must stay nonnegative and never increase. This catches a different class of mistakes, but still does not prove equivalence for every integer. Property selection is a specification activity. A malicious or overfit candidate can agree on visible examples while failing elsewhere. Keep held-out cases and use stronger methods when the domain or consequence demands them.
3. Read the implementation
Implementation excerpt from the companion. Run the complete lesson below with its imports and fixtures.
def behavior_check(candidate):
    valid = output_check(candidate)
    if valid.state != "pass":
        return valid
    expression = ast.parse(candidate["source"]).body[0].body[0].value
    try:
        for price, percent, expected in CASES:
            if interpret(expression, {"price": price, "percent": percent}) != expected:
                return Gate("revise", "behavior_mismatch")
    except (ArithmeticError, ValueError, KeyError, RecursionError):
        return Gate("reject", "arithmetic_failure")
    return Gate("pass", "behavior_examples_pass")
Specify the function's input domain separately: integer price >= 0 and integer percent in [0,100], with host validation before invocation in an actual service. The lab's trusted examples already satisfy that domain. Do not read the interpreted function as a complete pricing API. TypeSafe's documented numeric limitations reinforce the division of labor [1], but no model-specific result is needed to justify exact tests. The observable outcome here is decisive: shape=pass, behavior=revise; after replacing the formula with price * (100 - percent) // 100, behavior=pass.
4. Compare the outcomes
| Approach | Observable outcome |
|---|---|
| Before this control | Valid syntax and a persuasive explanation conceal wrong results. |
| After this control | An independent expected value catches the wrong formula. |
The following output comes from scripted fixtures that verify architecture behavior. It is not a measurement of live Jev accuracy, latency, or cost.
{
  "shape": "pass",
  "behavior": "revise",
  "fixed": "pass",
  "trusted_examples": 6
}
5. Run, break, and explain
Part 11 code · Implementation · Tests: test_shape_does_not_imply_behavior · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 11
python3 -m unittest tests.test_boundaries.BoundaryTests.test_shape_does_not_imply_behavior -v
Your turn
Create a formula that passes one visible example but fails a boundary case. Add a property that catches it without copying its implementation.
Keep three artifacts: the input you tried, the resulting state and reason, and an explanation of which boundary owns that result. Do not change an expected result merely to make a test pass.
6. Sources and limits
Primary sources and evidence limits
Sources checked 2 November 2026. Examples and thresholds are teaching designs. Inline [1], [2] follow the order below. Live API performance has not been measured.
- TypeSafe, Jev 1.13 jaggedness — Math and NumbersVersion-specific motivation for keeping exact arithmetic in code.