
ในบทความนี้
In this post
1. ปัญหาทางวิศวกรรม
เป้าหมายบทนี้
เริ่มจากงานที่โปรแกรมเมอร์คุ้นเคย แยกหน้าที่ AI-Core, Jev, function และ skill แล้วนิยามผลสำเร็จที่ตรวจได้
พื้นฐานที่ใช้: อ่าน function, dictionary และ test ง่าย ๆ ได้ ใช้ Python 3.11+ และ Git ไม่ต้องมีบัญชีโมเดลสำหรับแล็บออฟไลน์ อ่านบทก่อน แล้วรันแล็บและจดผลตามหัวข้อ 5
โปรแกรมแบบเดิมมีเงื่อนไขที่คนเขียนเปิดอ่านได้ เมื่อเพิ่มโมเดลเข้ามา เราเพิ่มส่วนที่ตีความภาษาจากสิ่งที่เรียนรู้ หน้าที่วิศวกรจึงต้องระบุว่าจุดใดควรใช้การตีความ และผลที่ตามมาจุดใดต้องอยู่ใต้โค้ดปกติ เรื่องคำนวณ สิทธิ์ และการเปลี่ยนสถานะที่มีกติกาชัดยังควรเขียนเป็นโค้ด การเรียกโมเดลแทนทุก if ทำให้งานที่ตอบได้แน่นอนมีความไม่แน่นอนเพิ่มขึ้นโดยไม่จำเป็น
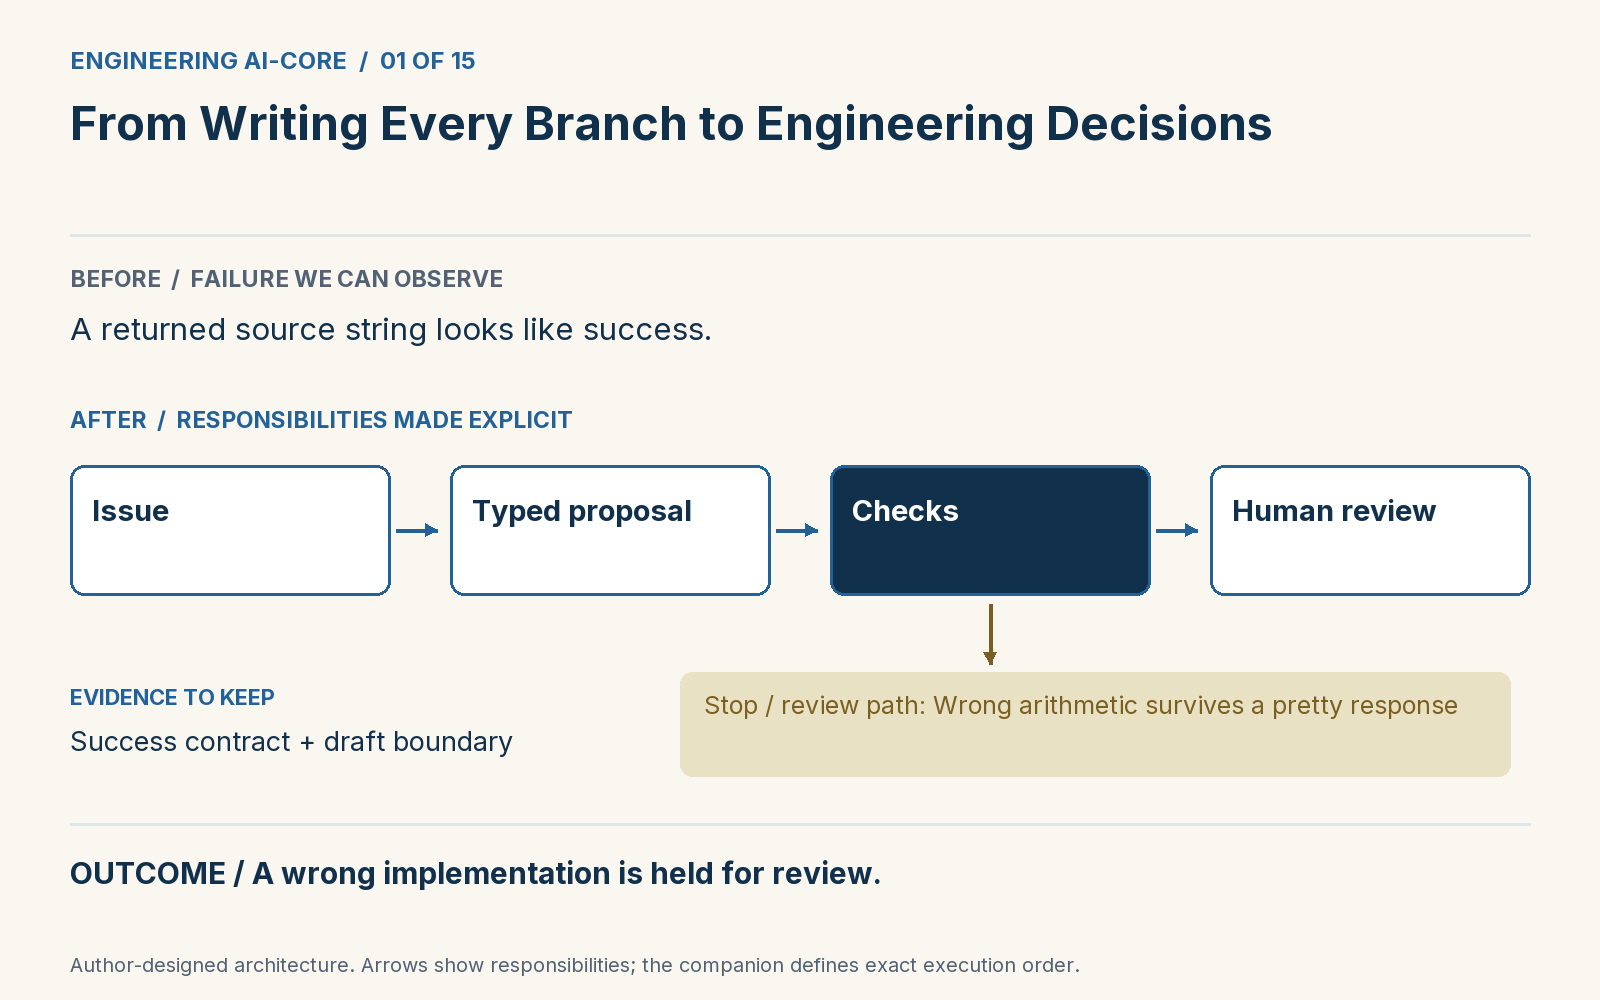
ตัวอย่างตลอดคอร์สคือ Patch Workbench รับ issue เลือก skill ที่ทีมตรวจแล้ว สร้างร่างฟังก์ชันราคา ตรวจร่าง ประเมินคำอธิบาย และส่งให้ maintainer พิจารณา โจทย์เล็กพอให้ตามทัน: discount_cents(price, percent) ใช้หน่วยเซนต์จำนวนเต็มและปัดผลลง ราคา 1,999 เซนต์ลด 25 เปอร์เซ็นต์ต้องเหลือ 1,499 เซนต์ ร่างที่คืน price ลบ percent เป็น Python ที่เขียนถูกไวยากรณ์แต่แก้โจทย์ผิด เราจะใช้กรณีนี้ติดตามความต่างของแต่ละด่าน
2. ขอบเขตที่ต้องออกแบบ
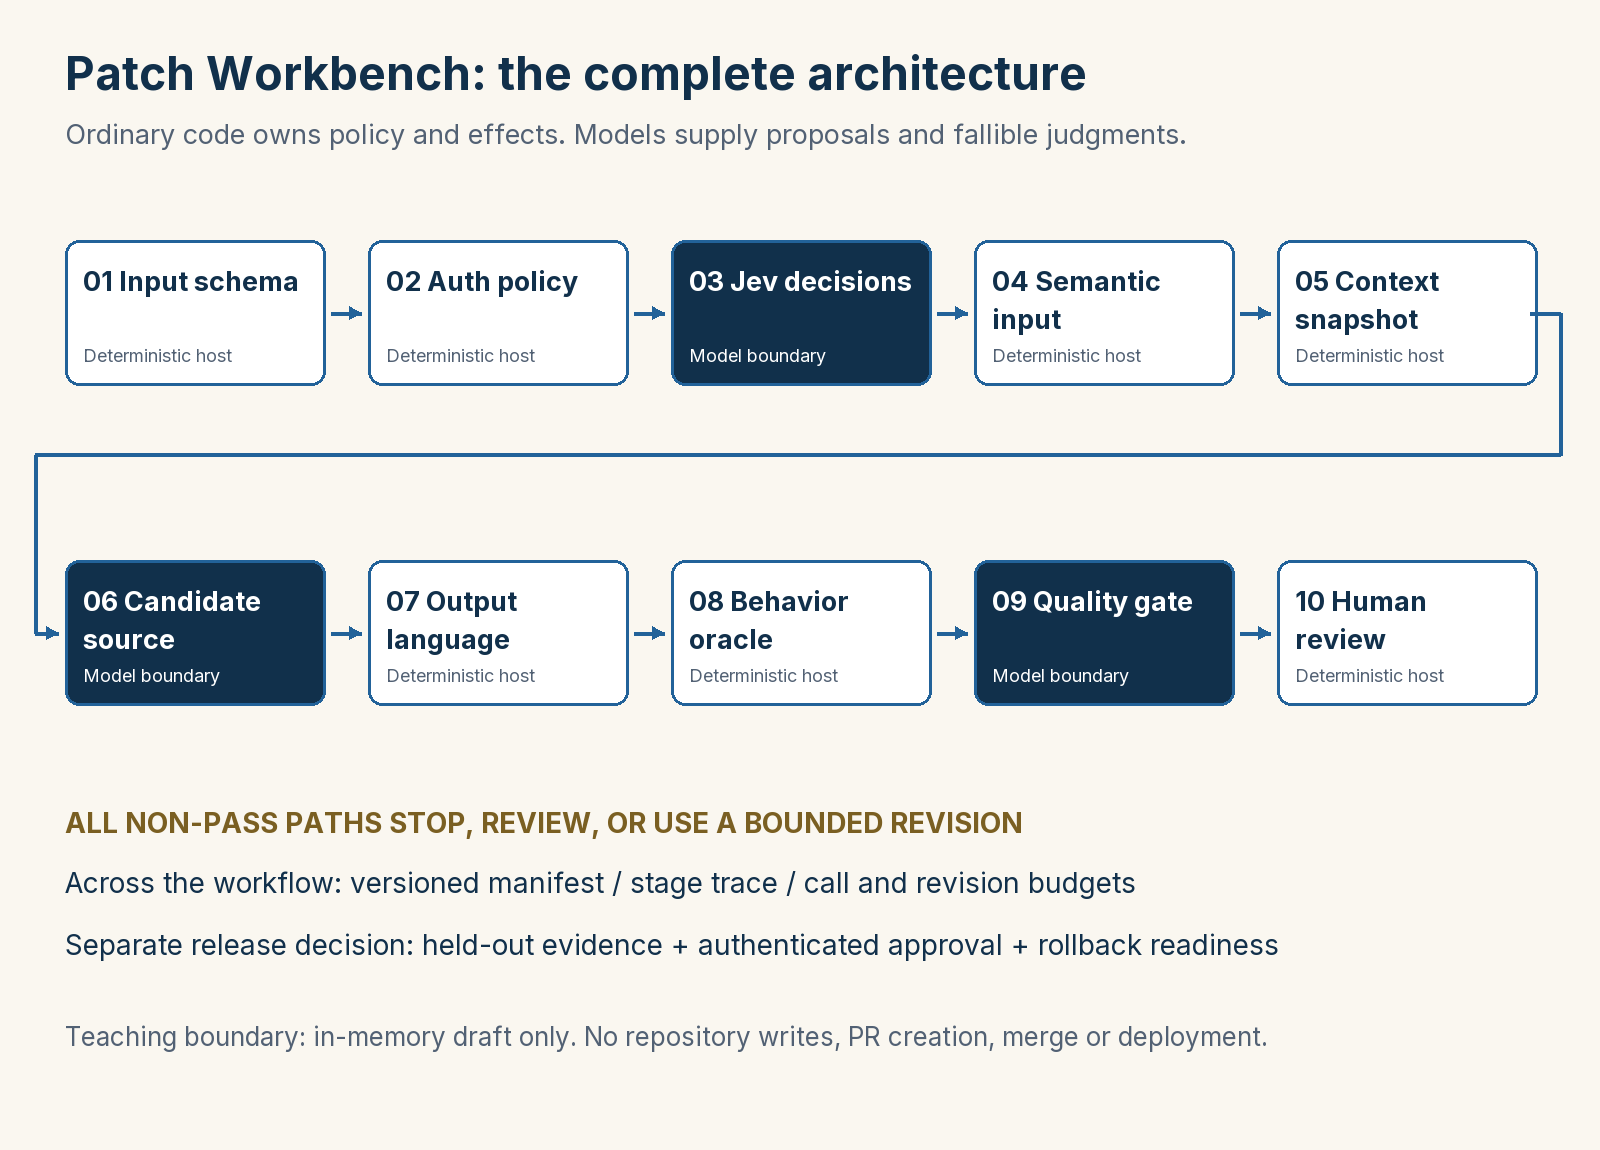
แยกคำสี่คำให้ชัด function แปลงค่าที่ระบุแน่นอน skill รวมคำแนะนำและทรัพยากรของงานที่ผ่านการตรวจ Jev ให้คำตัดสินแบบมีชนิดข้อมูลจาก state ส่วนโมเดลสร้างข้อความใช้เสนอ code หรือคำอธิบาย สำหรับ AI-Core ต้องถามต่อว่า runtime พึ่งการตัดสินของโมเดลเพียงใด และโมเดลมีอำนาจต่อผลลัพธ์แค่ไหน การใช้ AI ช่วยเขียน service ที่ทำงานตามกฎเดิมยังไม่พอจะเรียก service นั้นว่า AI-Core ตัวอย่างในคอร์สเป็นเครื่องมือร่างงานที่จำกัดอำนาจ ไม่ได้อ้างว่าพิสูจน์ความขาดไม่ได้ของโมเดลแล้ว
3. อ่าน implementation
ส่วนโค้ดจาก companion เพื่ออ่านประกอบ ใช้คำสั่งในหัวข้อ 5 เพื่อรันตัวอย่างที่ครบ dependency
from workbench.runtime import candidate
from workbench.core import output_check, behavior_check

# Familiar deterministic implementation
def discount_cents(price, percent):
    return price * (100 - percent) // 100

assert discount_cents(1999, 25) == 1499

# A plausible generated proposal still needs independent checks
proposal = candidate("def discount_cents(price, percent):\n    return price - percent\n")
print(output_check(proposal).state)    # pass: permitted shape
print(behavior_check(proposal).state)  # revise: wrong behavior
เริ่มด้วยสัญญาความสำเร็จ: issue อยู่ในขอบเขต มีสิทธิ์ใน repository ภาษาโค้ดอยู่ในชุดที่อนุญาต พฤติกรรมที่ตรวจผ่าน คำอธิบายมีประโยชน์ และยังไม่มีผลภายนอก accepted_draft หมายถึงร่างพร้อมให้มนุษย์ตรวจ ไม่ได้หมายถึง merge, deploy หรือพิสูจน์ถูกทุก input แนวแยก workflow กับ agent ของ Anthropic ช่วยอธิบายว่าทำไมงานนี้เริ่มด้วยทางเดินที่โค้ดกำหนด [1] ส่วนการเริ่มจากขอบเขตร่างเป็นการตัดสินใจออกแบบของคอร์ส แล้วค่อยเพิ่มความซับซ้อนเมื่อพบความล้มเหลวที่ชัดเจน
4. เปรียบเทียบผลที่ได้
| เส้นทาง | ผลที่สังเกตได้ |
|---|---|
| ก่อนเพิ่มด่านนี้ | ได้ source กลับมาก็นับว่าสำเร็จ |
| หลังเพิ่มด่านนี้ | ร่างที่แก้โจทย์ผิดถูกพักไว้ให้ตรวจ |
ผลต่อไปนี้มาจาก fixture ที่กำหนดคำตอบไว้เพื่อตรวจสถาปัตยกรรม ไม่ใช่ผลวัดความแม่น ความเร็ว หรือต้นทุนของ Jev จริง
{
  "old_way": "returns a source string",
  "new_way": "review",
  "lesson": "A string is a proposal, not task success."
}
5. รัน ทำให้พัง และอธิบาย
Part 01 code · Implementation · Tests: test_shape_does_not_imply_behavior · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 1
python3 -m unittest tests.test_boundaries.BoundaryTests.test_shape_does_not_imply_behavior -v
ลองทำด้วยตัวเอง
เขียนสัญญาความสำเร็จของ feature ที่ทำอยู่ ระบุกฎที่ตรวจแน่นอนได้สามข้อ และการตีความที่ควรใช้โมเดลหนึ่งข้อ
สิ่งที่ต้องส่ง: input ที่ลอง สถานะและเหตุผลที่ได้ และคำอธิบายว่าด่านใดเป็นผู้รับผิดชอบ ห้ามแก้ expected result เพียงเพื่อให้ test ผ่าน
6. แหล่งอ้างอิงและขอบเขต
เอกสารต้นทางและข้อจำกัด
ตรวจเอกสาร 2 พฤศจิกายน 2026 ตัวอย่างและ threshold เป็นการออกแบบเพื่อการสอน การอ้าง [1], [2] ตรงกับลำดับข้างล่าง ยังไม่ได้วัด live API
- Anthropic, Building effective agents (2024)Workflow and agent distinction; complexity tradeoffs.
- Anirach, Engineering AI-Core SystemsRelated classification framework on this site.
1. The engineering problem
Learning outcome
Map familiar programming responsibilities onto AI-Core, Jev, functions and skills, then define a measurable outcome.
Prerequisites: basic functions, dictionaries and tests; Python 3.11+ and Git. Offline labs need no model account. Read the chapter, run its lab, and record the outcome in section 5.
A conventional program contains branches whose conditions a programmer can inspect. An AI workflow introduces a component whose interpretation of language is learned. The engineering problem is deciding where that interpretation is useful and which consequences remain governed by ordinary code. Replacing every if statement with a model call adds uncertainty to problems that already have exact answers. Keep arithmetic, authorization and explicit state transitions in code; use models where the input really needs interpretation.
Our running project is Patch Workbench: take a software issue, choose a reviewed skill, produce a candidate pricing function, validate it, assess its explanation, and return a draft for a maintainer. The requirement is deliberately small: discount_cents(price, percent) uses integer cents and rounds down. At 1,999 cents and 25 percent, the required result is 1,499 cents. A candidate that returns price minus percent is valid Python but solves the wrong problem. This one counterexample will travel through the course.
2. The boundary to design
Use four precise names. A function transforms explicit values. A skill packages reviewed instructions and resources for a task. Jev supplies typed judgments about supplied state; a generative model supplies proposed code or prose. AI-Core is the architectural question of how much deployed work depends on model decisions and how much authority those decisions hold. Coding a deterministic service with an AI assistant does not by itself make that service AI-Core. This tutorial's draft-only tool is a bounded example for studying those responsibilities, not an empirical claim of model indispensability.
3. Read the implementation
Implementation excerpt from the companion. Run the complete lesson below with its imports and fixtures.
from workbench.runtime import candidate
from workbench.core import output_check, behavior_check

# Familiar deterministic implementation
def discount_cents(price, percent):
    return price * (100 - percent) // 100

assert discount_cents(1999, 25) == 1499

# A plausible generated proposal still needs independent checks
proposal = candidate("def discount_cents(price, percent):\n    return price - percent\n")
print(output_check(proposal).state)    # pass: permitted shape
print(behavior_check(proposal).state)  # revise: wrong behavior
Start by writing a success contract: supported issue, authorized repository, allowed candidate language, correct observed behavior, useful explanation, and no external effect. The last condition is intentional: accepted_draft means ready for human review. It does not mean merged, deployed, or proven correct for every input. Anthropic's workflow/agent distinction supports choosing a fixed code path for this task [1]. Our decision to start with a narrow draft boundary is a course design choice. We will earn additional complexity only when a concrete failure makes it necessary.
4. Compare the outcomes
| Approach | Observable outcome |
|---|---|
| Before this control | A returned source string looks like success. |
| After this control | A wrong implementation is held for review. |
The following output comes from scripted fixtures that verify architecture behavior. It is not a measurement of live Jev accuracy, latency, or cost.
{
  "old_way": "returns a source string",
  "new_way": "review",
  "lesson": "A string is a proposal, not task success."
}
5. Run, break, and explain
Part 01 code · Implementation · Tests: test_shape_does_not_imply_behavior · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 1
python3 -m unittest tests.test_boundaries.BoundaryTests.test_shape_does_not_imply_behavior -v
Your turn
Write a success contract for one feature you currently implement by hand. List three exact rules and one judgment that needs a model.
Keep three artifacts: the input you tried, the resulting state and reason, and an explanation of which boundary owns that result. Do not change an expected result merely to make a test pass.
6. Sources and limits
Primary sources and evidence limits
Sources checked 2 November 2026. Examples and thresholds are teaching designs. Inline [1], [2] follow the order below. Live API performance has not been measured.
- Anthropic, Building effective agents (2024)Workflow and agent distinction; complexity tradeoffs.
- Anirach, Engineering AI-Core SystemsRelated classification framework on this site.