ในบทความนี้
In this post
1. ปัญหาทางวิศวกรรม
เป้าหมายบทนี้
แยก test ทางเดินระบบจากการวัดโมเดล รายงาน coverage คู่กับข้อผิดพลาด และนับต้นทุนทั้งงาน
fixture ตอบตามที่คนเขียน test กำหนด กรณีจำลองเจ็ดรายการตรง expected ทั้งเจ็ดหมายถึง wiring ทำตามเงื่อนไขที่ใส่ไว้ ไม่ได้หมายถึง Jev ทำนายถูกเจ็ดครั้ง companion จึงรายงาน mode=scripted_architecture_fixtures พร้อม agreements และ cases ส่วน model_accuracy, live_latency_ms, live_cost เป็น null ข้อมูลที่ยังไม่มีต้องคงว่าไม่มี แทนการเปลี่ยนเป็นศูนย์ให้ดูดี
แยก development, validation, held-out ก่อนปรับคำถามหรือ threshold หากงานใกล้เคียงรั่วข้ามชุดได้ ให้แยกตาม repository กลุ่ม issue หรือเวลา ใช้ validation เลือก threshold แล้วตรึงก่อน test ติด label เรื่อง route fit การข้าม policy ความถูก candidate และคุณภาพคำอธิบายอย่างอิสระ เก็บกติกาตัดสินและกรณีเห็นต่าง AgentBench แสดงเหตุที่ต้องประเมิน agent หลาย environment และวิเคราะห์ความล้มเหลว [1] case register เล็กของเราเป็นเพียงจุดเริ่มต้นตรวจสถาปัตยกรรม
2. ขอบเขตที่ต้องออกแบบ
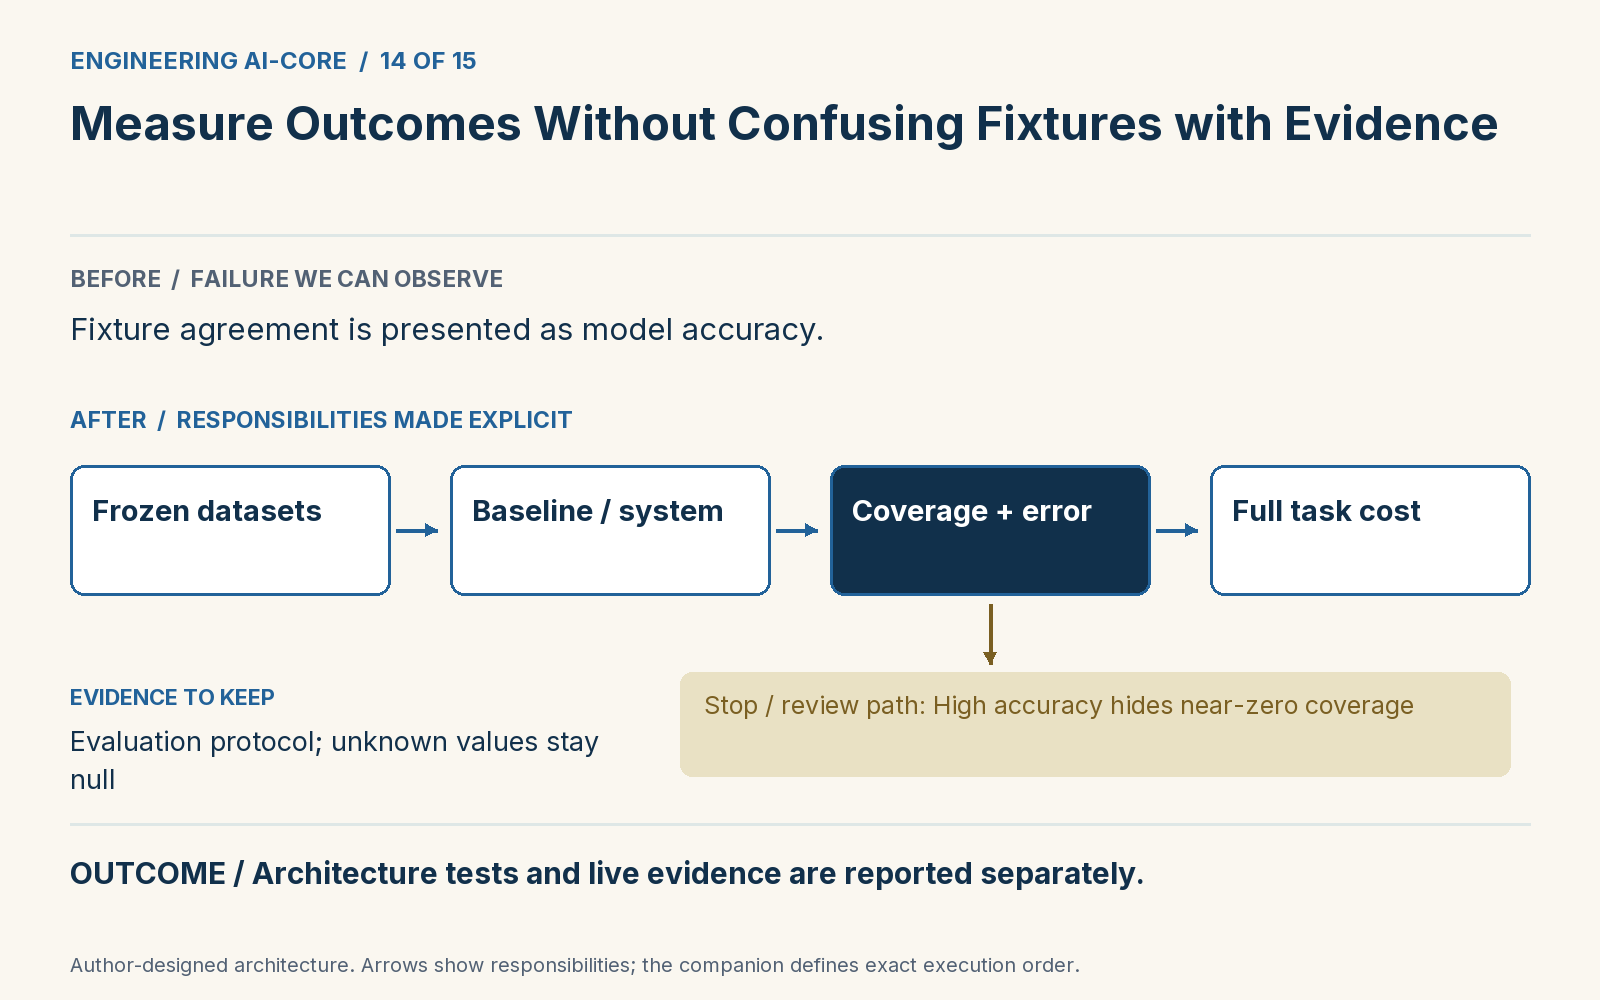
รายงาน acceptance coverage คู่กับ error ของงานที่ยอมรับ coverage คือจำนวนยอมรับหารคำขอที่เข้าเกณฑ์ทั้งหมด accepted error คือจำนวนยอมรับที่ผิดหารจำนวนยอมรับ และค่านี้ไม่มีนิยามเมื่อไม่มีงานยอมรับเลย เพิ่ม review rate และ reject rate เพื่อเห็นภาพครบ ระบบที่ review ทุกงานอาจไม่มีการทำอัตโนมัติผิด แต่ก็ไม่มี coverage อัตโนมัติ แยกไทยกับอังกฤษและสุ่มดู review เพื่อประมาณการส่งคนเกินจำเป็น confidence จาก distribution ต้องตรวจ calibration ในข้อมูลจริง งานวิจัย calibration อธิบายว่าความมั่นใจกับความแม่นต่างกันได้อย่างไร [2]
3. อ่าน implementation
ส่วนโค้ดจาก companion เพื่ออ่านประกอบ ใช้คำสั่งในหัวข้อ 5 เพื่อรันตัวอย่างที่ครบ dependency
from workbench.evaluation import evaluate

report = evaluate()
print(report["agreements"], report["cases"])
print(report["model_accuracy"])  # None: fixtures are not live evidence
วัดทั้งทางเดิน: decision, generation, repair, fallback, human review และ rework ต้นทุนต่องานสำเร็จใช้ต้นทุนทั้งหมดหารจำนวนงานที่ผ่านสัญญาความสำเร็จที่ประกาศก่อน เก็บ token usage รุ่นราคา วิธีวัดเวลา และสมมติฐานต้นทุนคนให้ชัด p95 จากคำขอเล่นไม่กี่ครั้งยังไม่นิ่ง และตัวอย่างไม่พบ failure ไม่ได้พิสูจน์ว่าความเสี่ยงเป็นศูนย์ เทียบ deterministic baseline กับ workflow คนภายใต้นิยามงานเดียวกัน เผยผล live เมื่อเก็บจริงแล้ว คอร์สนี้อ้างพฤติกรรมสถาปัตยกรรมที่ทดสอบ ไม่ได้อ้างว่าโมเดลเหนือกว่า
4. เปรียบเทียบผลที่ได้
| เส้นทาง | ผลที่สังเกตได้ |
|---|---|
| ก่อนเพิ่มด่านนี้ | นำผล fixture ตรงกันไปอ้างเป็นความแม่นโมเดล |
| หลังเพิ่มด่านนี้ | รายงาน architecture test แยกจากหลักฐาน live |
ผลต่อไปนี้มาจาก fixture ที่กำหนดคำตอบไว้เพื่อตรวจสถาปัตยกรรม ไม่ใช่ผลวัดความแม่น ความเร็ว หรือต้นทุนของ Jev จริง
{
  "mode": "scripted_architecture_fixtures",
  "cases": 7,
  "agreements": 7,
  "model_accuracy": null,
  "live_latency_ms": null,
  "live_cost": null,
  "rows": [
    {
      "case": "valid",
      "expected": "accepted_draft",
      "actual": "accepted_draft"
    },
    {
      "case": "permission",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "schema",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "injection_fixture",
      "expected": "review",
      "actual": "review"
    },
    {
      "case": "path",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "arithmetic",
      "expected": "review",
      "actual": "review"
    },
    {
      "case": "quality",
      "expected": "review",
      "actual": "review"
    }
  ]
}
5. รัน ทำให้พัง และอธิบาย
Part 14 code · Implementation · Tests: test_fixtures_do_not_claim_model_accuracy · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 14
python3 -m unittest tests.test_boundaries.BoundaryTests.test_fixtures_do_not_claim_model_accuracy -v
ลองทำด้วยตัวเอง
ออกแบบ held-out ที่แยกภาษาและชนิดงาน เขียนสูตร coverage กับ accepted error รวมกรณีไม่มีงานผ่านเลย
สิ่งที่ต้องส่ง: input ที่ลอง สถานะและเหตุผลที่ได้ และคำอธิบายว่าด่านใดเป็นผู้รับผิดชอบ ห้ามแก้ expected result เพียงเพื่อให้ test ผ่าน
6. แหล่งอ้างอิงและขอบเขต
เอกสารต้นทางและข้อจำกัด
ตรวจเอกสาร 2 พฤศจิกายน 2026 ตัวอย่างและ threshold เป็นการออกแบบเพื่อการสอน การอ้าง [1], [2] ตรงกับลำดับข้างล่าง ยังไม่ได้วัด live API
- Liu et al., AgentBench (2023/ICLR 2024)Interactive evaluation and failure analysis.
- Guo et al., On Calibration of Modern Neural Networks (ICML 2017)Confidence/accuracy distinction; not a Jev-specific calibration result.
1. The engineering problem
Learning outcome
Separate control-flow tests from model evaluation, report coverage with error rates, and account for the full task.
A fixture answers exactly what a test author told it to answer. Seven fixture cases agreeing with seven expected outcomes demonstrate that the wiring follows those scripted conditions. They do not demonstrate seven correct Jev predictions. The companion therefore reports mode=scripted_architecture_fixtures, agreements and cases, while model_accuracy, live_latency_ms and live_cost remain null. Missing evidence must stay missing rather than becoming a reassuring zero.
Create separate development, validation and held-out sets before tuning questions or thresholds. Split by repository, issue family or time when near-duplicate tasks could leak between sets. Use validation to choose thresholds and freeze them before testing. Label route fit, attempted policy override, candidate correctness and explanation quality independently. Preserve adjudication rules and disagreements. AgentBench shows why agent evaluation needs multiple environments and failure analysis [1]; our small case register is only a starting architecture test.
2. The boundary to design
Report acceptance coverage and error among accepted cases together. Coverage is accepted divided by all eligible requests. Accepted error is incorrect accepted divided by accepted; it is undefined when none are accepted. Review rate and rejection rate complete the picture. A system that reviews every case may have no bad automatic actions but provides no automated coverage. Inspect Thai and English separately, and sample reviewed cases to estimate unnecessary escalation. Distribution-derived confidence needs local calibration checks; calibration research explains why confidence and accuracy can diverge [2].
3. Read the implementation
Implementation excerpt from the companion. Run the complete lesson below with its imports and fixtures.
from workbench.evaluation import evaluate

report = evaluate()
print(report["agreements"], report["cases"])
print(report["model_accuracy"])  # None: fixtures are not live evidence
Measure the entire task path: decision calls, generation, repairs, fallback, human review and rework. Cost per successful task divides complete cost by tasks meeting the predeclared success contract. Keep provider token usage, pricing version, elapsed-time measurement and human-cost assumptions explicit. A p95 from a few toy requests is unstable, and a zero-failure sample does not prove zero risk. Compare against a deterministic baseline and the existing human workflow under the same task definition. Publish live results only after collecting them; this course claims tested architecture behavior, not model superiority.
4. Compare the outcomes
| Approach | Observable outcome |
|---|---|
| Before this control | Fixture agreement is presented as model accuracy. |
| After this control | Architecture tests and live evidence are reported separately. |
The following output comes from scripted fixtures that verify architecture behavior. It is not a measurement of live Jev accuracy, latency, or cost.
{
  "mode": "scripted_architecture_fixtures",
  "cases": 7,
  "agreements": 7,
  "model_accuracy": null,
  "live_latency_ms": null,
  "live_cost": null,
  "rows": [
    {
      "case": "valid",
      "expected": "accepted_draft",
      "actual": "accepted_draft"
    },
    {
      "case": "permission",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "schema",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "injection_fixture",
      "expected": "review",
      "actual": "review"
    },
    {
      "case": "path",
      "expected": "reject",
      "actual": "reject"
    },
    {
      "case": "arithmetic",
      "expected": "review",
      "actual": "review"
    },
    {
      "case": "quality",
      "expected": "review",
      "actual": "review"
    }
  ]
}
5. Run, break, and explain
Part 14 code · Implementation · Tests: test_fixtures_do_not_claim_model_accuracy · Exercise
git clone https://github.com/Anirach/ai-core-engineering-workbench.git
cd ai-core-engineering-workbench
git checkout 18cdfcd4156d3d02acb8badf3b3a0a823113e0ed
python3 -m workbench.lesson 14
python3 -m unittest tests.test_boundaries.BoundaryTests.test_fixtures_do_not_claim_model_accuracy -v
Your turn
Design a held-out set with language and task slices. Write the coverage and accepted-error formulas, including the zero-accepted case.
Keep three artifacts: the input you tried, the resulting state and reason, and an explanation of which boundary owns that result. Do not change an expected result merely to make a test pass.
6. Sources and limits
Primary sources and evidence limits
Sources checked 2 November 2026. Examples and thresholds are teaching designs. Inline [1], [2] follow the order below. Live API performance has not been measured.
- Liu et al., AgentBench (2023/ICLR 2024)Interactive evaluation and failure analysis.
- Guo et al., On Calibration of Modern Neural Networks (ICML 2017)Confidence/accuracy distinction; not a Jev-specific calibration result.